Issue 51Published September 26, 2026
Editor noteThis archived Ash AI Daily issue retains the delivered editorial briefing and final cards.
 Ash SystemsAI NewsletterDaily Issue
Four verified releases for builders: AI-cloud financing, physical-agent perception, text-to-audio and speaker-aware transcription.
This archived Ash AI Daily issue retains the delivered editorial briefing and final cards.
Each story keeps its image, summary, impact, and linked sources in one uninterrupted reading flow.
This archived Ash AI Daily issue retains the delivered editorial briefing and final cards.
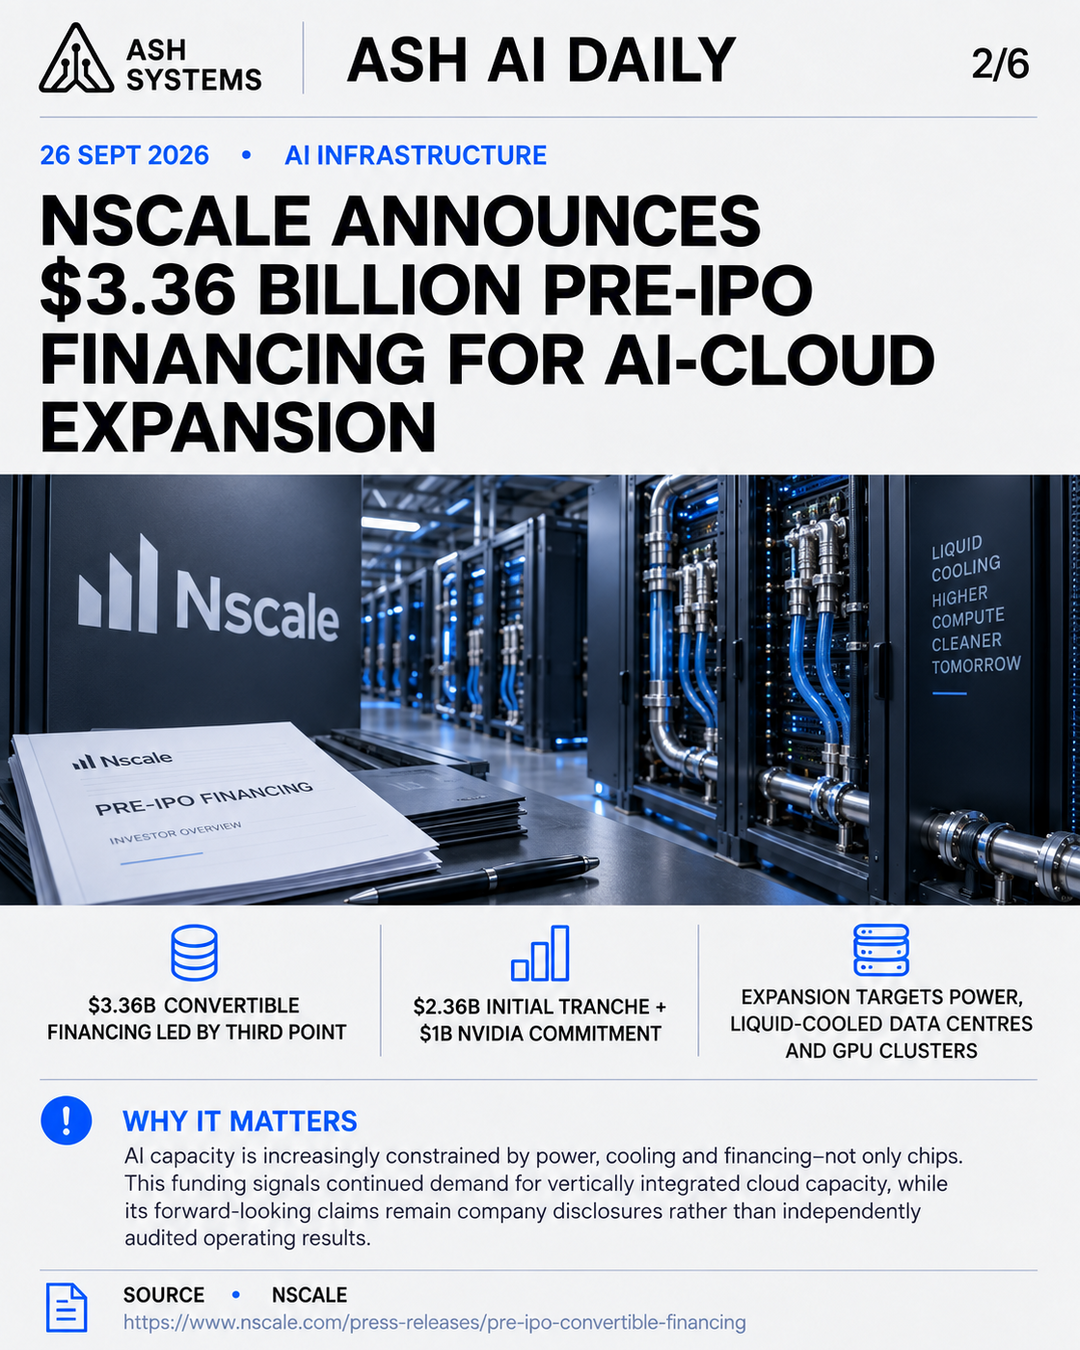
AI Infrastructure. Nscale announced $3.36 billion in convertible loan-note financing led by Third Point. The company says the package comprises a $2.36 billion initial tranche and a further $1 billion NVIDIA commitment expected in November, supporting expansion across power, liquid-cooled data centres and GPU clusters.
AI capacity is increasingly constrained by power, cooling and financing—not only chips. The company’s growth and contract-value claims remain forward-looking disclosures rather than independently audited operating results.
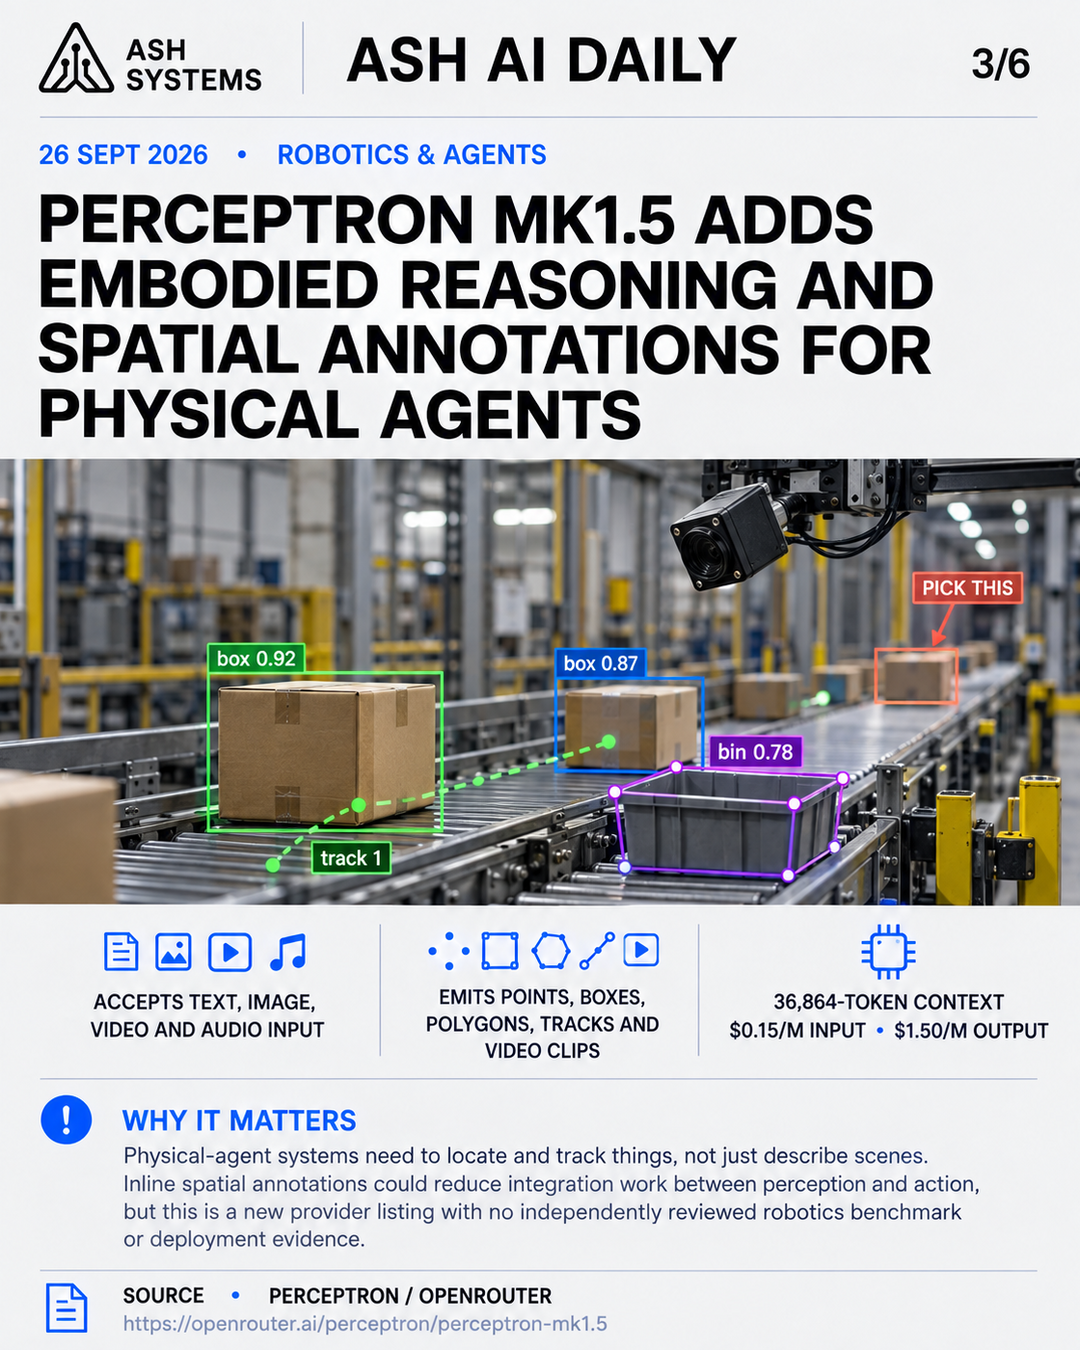
Robotics & Agents. Perceptron Mk1.5 accepts text, images, video and audio, returning text with optional points, boxes, polygons, tracks and video clips. The listing gives a 36,864-token context window and prices of $0.15 per million input tokens and $1.50 per million output tokens.
Physical agents need to locate and track things, not merely describe scenes. The integration promise is meaningful, but this is provider-listed capability data without an independently reviewed robotics benchmark or deployment study.
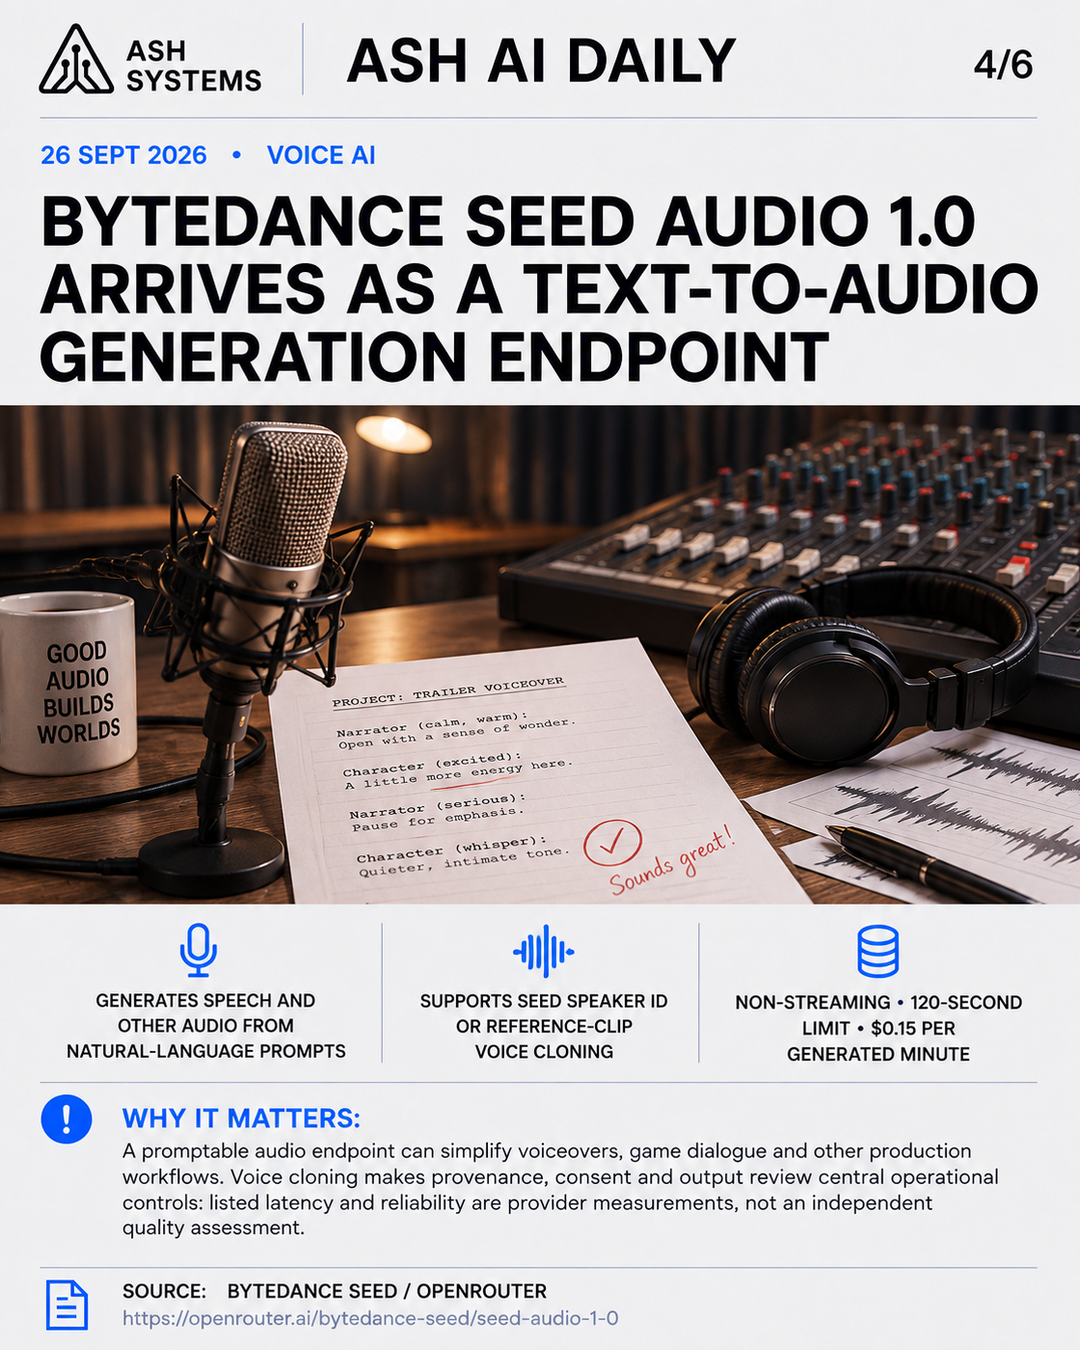
Voice AI. Seed Audio 1.0 generates speech and other audio from natural-language prompts, with an optional Seed speaker ID or reference audio clip for voice cloning. It is non-streaming, limited to 120 seconds per request and listed at $0.15 per generated minute.
Promptable audio can simplify voiceovers, game dialogue and production workflows. Because voice cloning heightens consent and provenance risk, teams should separately assess rights controls and quality; listed operations metrics are provider data.
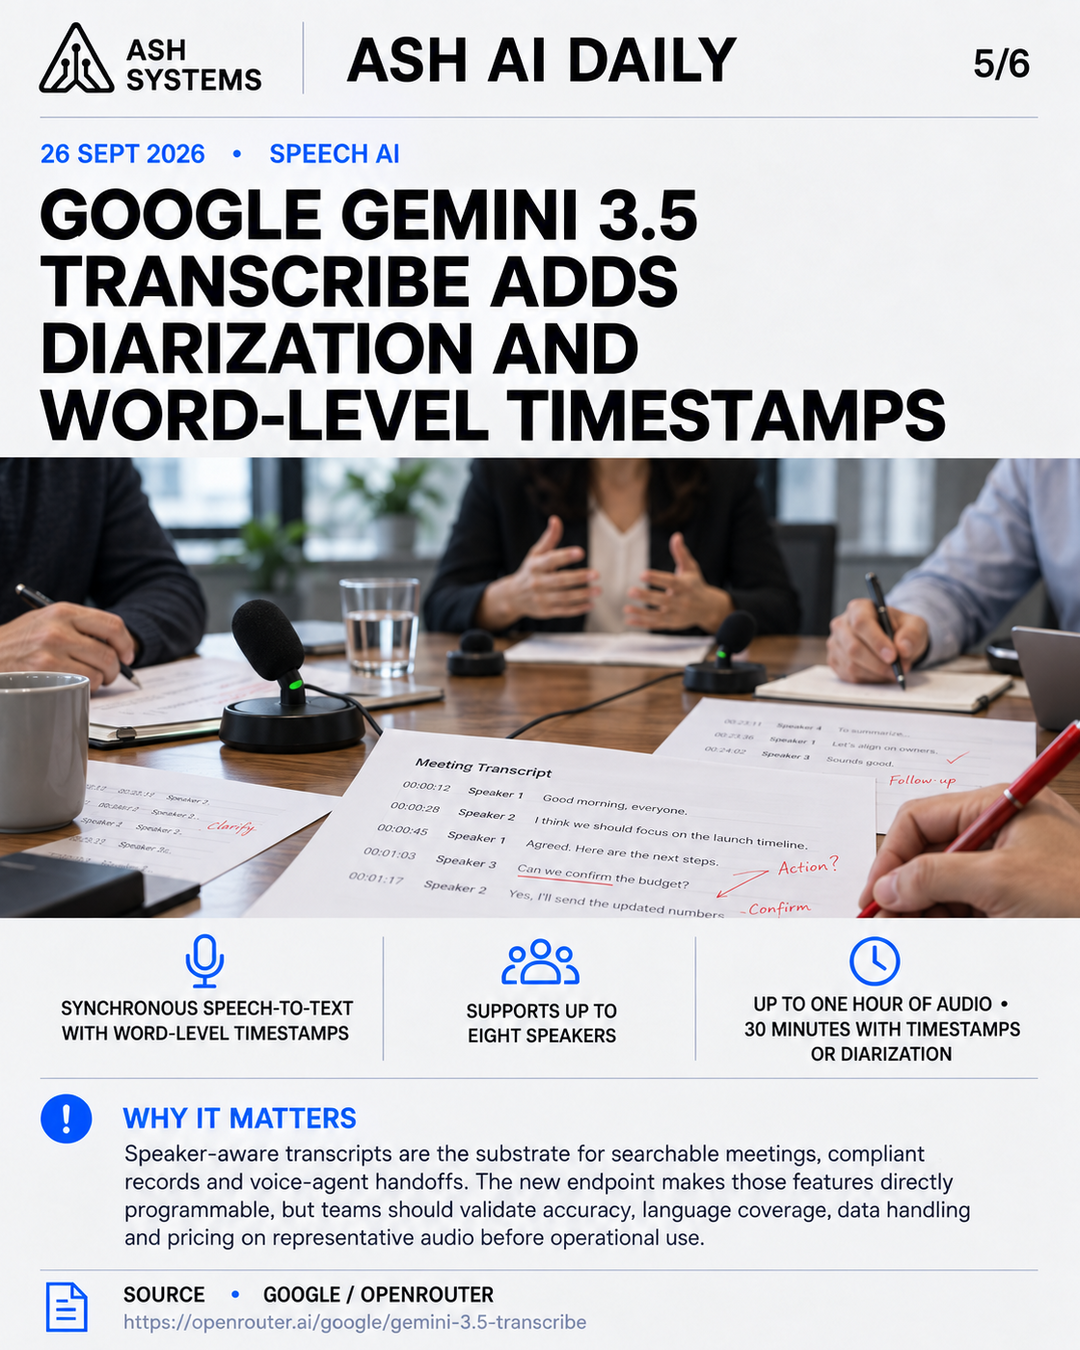
Speech AI. Gemini 3.5 Transcribe is listed as a synchronous speech-to-text model with word-level timestamps and speaker diarization for up to eight speakers. It supports up to one hour of audio, or 30 minutes when timestamps or diarization are enabled.
Speaker-aware transcripts are the substrate for searchable meetings, compliant records and voice-agent handoffs. The endpoint makes those features programmable, but teams should validate accuracy, language coverage, data handling and price on representative audio.
This issue includes a closing visual to carry the next-day watchlist or wrap-up prompt alongside the main briefing.
Join the source-linked daily briefing and confirm once before delivery begins.
Ash AI Daily

A concise, source-linked read on the AI news that changes what teams can build.
You will receive a confirmation email before any daily issue is sent.