Issue 45Published September 20, 2026
Editor noteThis archived Ash AI Daily issue retains the delivered editorial briefing and final cards.
 Ash SystemsAI NewsletterDaily Issue
An independent, reproducible measurement dataset adds a fresh operational view of AI inference performance across providers and regions.
This archived Ash AI Daily issue retains the delivered editorial briefing and final cards.
Each story keeps its image, summary, impact, and linked sources in one uninterrupted reading flow.
This archived Ash AI Daily issue retains the delivered editorial briefing and final cards.
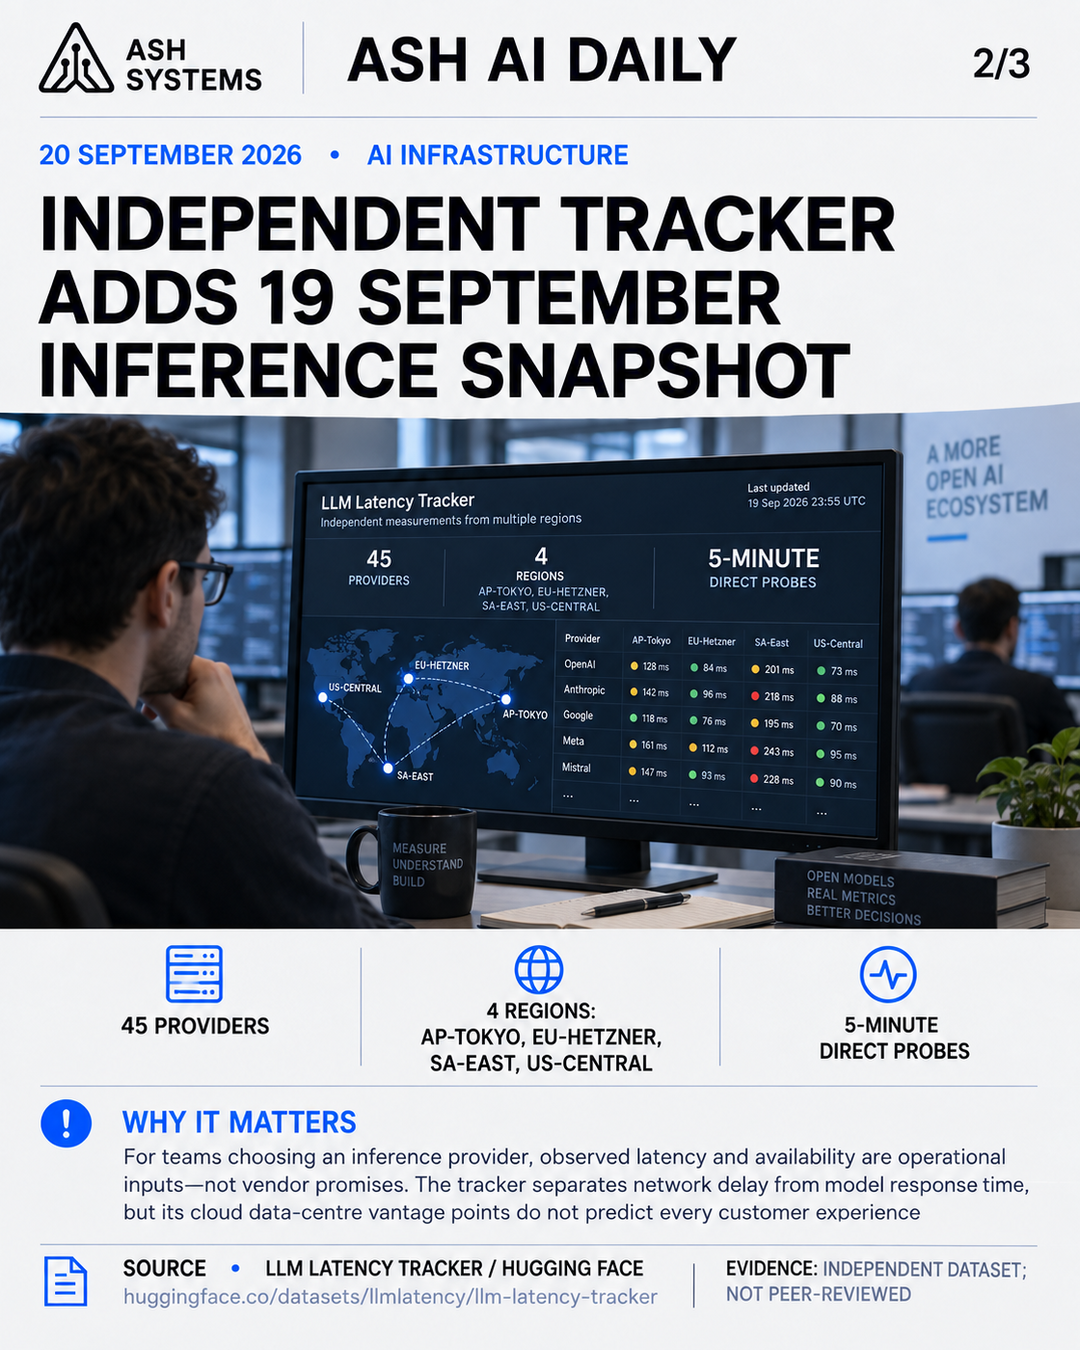
The LLM Latency Tracker published a 19 September data snapshot covering 45 inference providers across ap-tokyo, eu-hetzner, sa-east and us-central. Its methodology says probes run every five minutes directly to providers and separately reports network time-to-first-byte and inference time-to-first-token. The repository records the snapshot at 07:50 UTC; it is an independent dataset, not peer-reviewed research.
For teams selecting inference capacity, observed availability and latency are operational inputs rather than vendor claims. The separation between network delay and model response time makes the data more useful for diagnosis, while its cloud data-centre vantage points mean it cannot predict every customer experience.
This issue includes a closing visual to carry the next-day watchlist or wrap-up prompt alongside the main briefing.
Join the source-linked daily briefing and confirm once before delivery begins.
Ash AI Daily

A concise, source-linked read on the AI news that changes what teams can build.
You will receive a confirmation email before any daily issue is sent.