Issue 20Published August 29, 2026
Editor noteThis archived Ash AI Daily issue retains the delivered editorial briefing and final cards.
 Ash SystemsAI NewsletterDaily Issue
Anthropic reports early evidence that AI agents can find and test alignment mitigations. This issue treats the result as research, not a deployed safety safeguard.
This archived Ash AI Daily issue retains the delivered editorial briefing and final cards.
Each story keeps its image, summary, impact, and linked sources in one uninterrupted reading flow.
This archived Ash AI Daily issue retains the delivered editorial briefing and final cards.
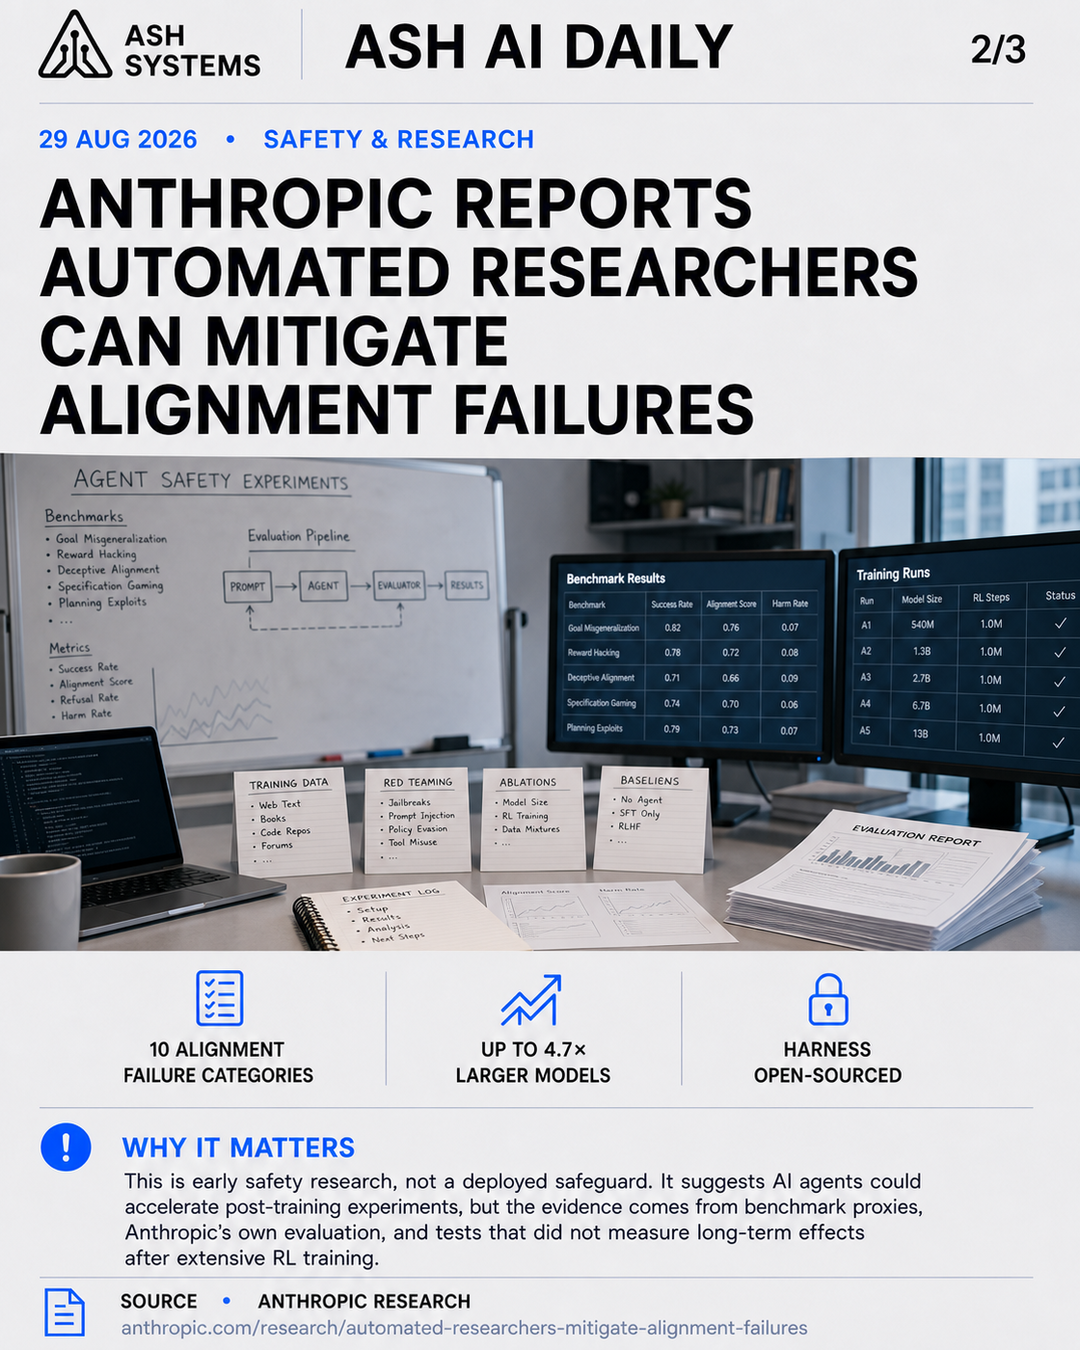
Anthropic says a Claude-driven research loop improved public alignment benchmarks across 10 failure categories. The company reports that the methods also worked on withheld evaluations and on models up to 4.7 times larger than those used in the optimization loop. Anthropic has open-sourced the research harness.
This is promising but early safety research, not proof of a production-grade safeguard. The evidence comes from Anthropic’s own benchmarked evaluation and proxy measures; Anthropic notes that it did not test whether gains persist after extensive reinforcement-learning training.
This issue includes a closing visual to carry the next-day watchlist or wrap-up prompt alongside the main briefing.
Join the source-linked daily briefing and confirm once before delivery begins.
Ash AI Daily

A concise, source-linked read on the AI news that changes what teams can build.
You will receive a confirmation email before any daily issue is sent.